Breaking News
 "Begin Preparing Yourself..." - Jeffrey Sachs
 The 5-Year Treasury Just Broke 5%... The Whole Curve Is Next
 ICE Denounced for Enacting 'Official Government Policy of Disappearing People'
 Google Just Told Canadian Adults: Give Us Your ID and a Selfie Or Else…And It's Starting Now!!
Top Tech News
 Tesla Model 3 killer charges from 10 to 97% in just 9 minutes
 World-first unpowered DNA computer sets speed record
 I Power 5 Buildings Off-Grid. Here's How
 The US government is pushing hard to get a working nuclear fission reactor into space by late 2028
 SpaceX Starmind AI in Space Radiator
 China Will Dominate Global Nuclear Energy Through 2035, Analyst Says
 These Absolutely Wild-Looking EVs Are Saudi Arabia's First Homegrown Cars
 BEYOND THE MOON: NASA plans a nuclear-powered fleet to push DEEPER into space
 Big Oil Backs Mazama's $135 Million Bet On Superhot Geothermal
 Quantum compass takes flight on Northrop's Lumberjack drone
AI voice cloning from a few seconds of voice sampling is real and rapidly improving
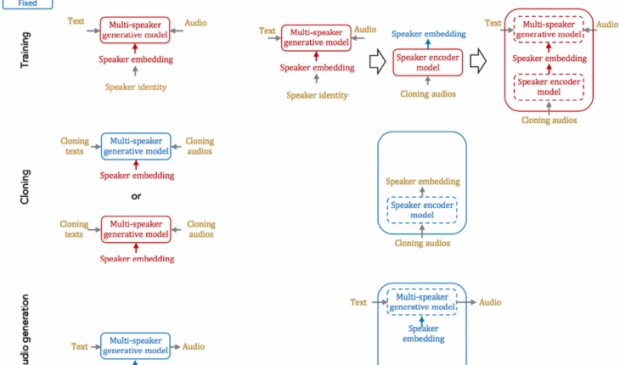
There are examples of speech sample recordings and synthesized speech based on different numbers of samples. The synthesized speech had some noise distortion but the samples did sound like the original speakers.
Baidu attempted to learn speaker characteristics from only a few utterances (i.e., sentences of few seconds duration). This problem is commonly known as "voice cloning." Voice cloning is expected to have significant applications in the direction of personalization in human-machine interfaces.
They tried two fundamental approaches for solving the problems with voice cloning: speaker adaptation and speaker encoding.
Speaker adaptation is based on fine-tuning a multi-speaker generative model with a few cloning samples, by using backpropagation-based optimization. Adaptation can be applied to the whole model, or only the low-dimensional speaker embeddings. The latter enables a much lower number of parameters to represent each speaker, albeit it yields a longer cloning time and lower audio quality.